Dr. Yuxiang Shang | Computer Science | Best Researcher Award
Dr. Yuxiang Shang’s research in Computer Science focuses on computational technologies, scholarly information systems, digital research infrastructure, and data-driven analysis. His academic profile reflects interests in emerging computing methodologies, research evaluation, bibliographic analysis, and technology-enabled approaches supporting knowledge discovery and innovation. Global Scholar Awards 🌟 Visit Our Website 🌐: globalscholarawards.com Nominate Now👍: https://globalscholarawards.com/doctor-awards-nobel-prize-scientists-award-nomination/?ecategory=Awards&rcategory=Awardee Contact us ✉️: info@globalscholarawards.com Get Connected Here: ================= Twitter : x.com/ScienceInventi1 Youtube : youtube.com/@nesinconferenceandawards4869 Pinterest : in.pinterest.com/scienceinventions/ Instagram : instagram.com/global_scholar_123 Linkedin : linkedin.com/in/global-scholar-awards-09664427b Blog : newscienceinventions2020.blogspot.com @WorldResearchAwards @GlobalScholarAwards #worldresearchawards #researchawards #researchexcellence #globalrecognition #academicawards #globalresearchawards #shorts #researchers #labtechnicians #awards #professors #teachers #lecturers #business

Mr. Erli Lin | Materials Science | Best Researcher Award
Mr. Erli Lin’s research in Materials Science focuses on surface engineering, electrochemical anodization, corrosion-resistant composite oxide coatings, magnesium alloys, and advanced energy-storage materials. His work includes protective coatings for magnesium alloys, nanostructured lithium-ion battery anodes, biodegradable implant materials, and multifunctional electrochemical architectures, reflecting interdisciplinary contributions to advanced materials development and sustainable energy technologies. Global Scholar Awards 🌟 Visit Our Website 🌐: globalscholarawards.com Nominate Now👍: https://globalscholarawards.com/doctor-awards-nobel-prize-scientists-award-nomination/?ecategory=Awards&rcategory=Awardee Contact us ✉️: info@globalscholarawards.com Get Connected Here: ================= Twitter : x.com/ScienceInventi1 Youtube : youtube.com/@nesinconferenceandawards4869 Pinterest : in.pinterest.com/scienceinventions/ Instagram : instagram.com/global_scholar_123 Linkedin : linkedin.com/in/global-scholar-awards-09664427b Blog : newscienceinventions2020.blogspot.com @WorldResearchAwards @GlobalScholarAwards #worldresearchawards #researchawards #researchexcellence #globalrecognition #academicawards #globalresearchawards #shorts #researchers #labtechnicians #awards #professors #teachers #lecturers #materialscience
Global Scholar Awards – Celebrating Research Excellence
Global Scholar Awards celebrates outstanding researchers, innovators, scholars, and institutions worldwide, recognizing impactful contributions, groundbreaking discoveries, innovation, collaboration, and excellence across diverse scientific and academic disciplines. Global Scholar Awards 🌟 Visit Our Website 🌐: globalscholarawards.com Nominate Now👍: https://globalscholarawards.com/doctor-awards-nobel-prize-scientists-award-nomination/?ecategory=Awards&rcategory=Awardee Contact us ✉️: info@globalscholarawards.com Get Connected Here: ================= Twitter : x.com/ScienceInventi1 Youtube : youtube.com/@nesinconferenceandawards4869 Pinterest : in.pinterest.com/scienceinventions/ Instagram : instagram.com/global_scholar_123 Linkedin : linkedin.com/in/global-scholar-awards-09664427b Blog : newscienceinventions2020.blogspot.com @WorldResearchAwards @GlobalScholarAwards #worldresearchawards #researchawards #researchexcellence #globalrecognition #academicawards #globalresearchawards #shorts #researchers #labtechnicians #awards #professors #teachers #lecturers
Grounding AI Agents: literature vs. structured databases in the biopharma data stack
Sharing perspectives from the hubXchange 2026 Roundtable: “Assembling the data stack: what pharma needs from external knowledge in the age of AI Agents”
As biopharmaceutical R&D transitions toward autonomous AI agents, the industry is forced to re-examine the core substrate upon which these agents reason. A critical roundtable discussion hosted by Digital Science at the AI in Drug Discovery hubXchange 2026 addressed a foundational bottleneck: How do we balance unstructured literature with specialized structured databases to build an AI-ready data stack?
The consensus was clear: while LLMs excel at parsing the vast sea of academic literature, they frequently struggle with structured data, exposing a deep division between literature consumption and structured database integration. In this article, we recap key insights from the roundtable discussion, and propose what this means for biopharma companies moving forward.
Unstructured literature: the promise and pitfalls of unstructured text
For many drug discovery teams, the primary value of Large Language Models (LLMs) today lies in their ability to conquer the sheer volume of academic literature. LLMs have dramatically optimized literature reviews by embedding text and measuring similar prompts across databases, removing the manual burden of reading endless papers.
However, relying strictly on LLMs introduces several acute pain points:
- The ingestion bottleneck: While LLMs are excellent at reading text, they struggle to extract data from tables, images, and graphs. Roundtable participants highlighted that automated, validated methods to draw conclusions from tables—for example, answering, “Here are the top things you need to know in this table”—remain a critical visual gap.
- The challenge of novelty: Experiments like Datasetpapers.com demonstrate that LLMs struggle to discover ‘unknown unknowns.’ True discovery requires explaining why a paper is groundbreaking or identifying novelty—a cognitive task where generative AI still struggles.
- The content quality spectrum: Literature quality varies wildly. Curated papers from established publishers represent a far more reliable substrate than unvetted public repositories.
- The missing negative results: A systemic bias exists where researchers are disincentivized from publishing negative results. In the AI age, dumping and organizing negative data must be simplified and incentivized (perhaps via shifts in H-index or S-index metrics) because machine learning models require negative data as much as positive data to build accurate classifiers.
‘Other’ databases: the cost and fragility of structured data
When moving beyond text consumption into computational biology and machine learning, biopharma relies on ‘other’ databases, such as structured sequence, mutation, chemical and clinical databases (e.g., UK Biobank, Gene PC, ADDI and PPMI for biomarker discovery validation).
These databases present a completely different set of challenges:
- A scarcity of domain databases: There is a severe lack of structured databases in highly specific areas, such as amino acid mutations. Traditional structural models versus sequence-based models remain a continuous pain point.
- The curation and funding crisis: Unlike the commercial publisher ecosystem, specialized public databases suffer from a chronic lack of ongoing funding. Representing this data, maintaining standards, and keeping it up to date is highly expensive. While large pharmaceutical corporations can absorb these costs, smaller biotech startups are effectively locked out.
- The funding shift: Government and national lab funding is increasingly shifting away from pharmaceutical R&D toward materials and closed-loop discovery, leaving national standards (such as those from NIST) updated frequently but lacking deep biological curation resources.
- Fouled public repositories: Without consistent curation and funding, public repositories easily become fouled with incorrect or mislabeled data. Because machine learning models are incredibly picky with data quality, many biopharma organizations are moving toward training models strictly with internal, highly-vetted data or avoiding public repositories altogether.
Harmonization: bridging the divide
The ultimate breakdown in the biopharma data stack occurs when attempting to harmonize unstructured literature findings with structured external databases and internal R&D data.
To make external data truly AI-ready, members of the roundtable discussed addressing several key operational requirements for their specific use cases and data needs:
- Defining clean data extraction standards: Clean data must go deeper than prose. In assay standards, data in the ‘methods’ section must be pristine and explicitly represent both positive and negative results.
- The metadata connection: Databases that rely on vague terms like ‘sample’ are highly problematic. Every raw read must be rigorously connected to downstream metadata, including omics data, patient profiles and study protocols.
- The missing donor ledger: A glaring gap in the current data stack is the lack of an interconnected, harmonized database of human blood and tissue donor identifiers.
- Re-identification risks: As AI agents cross-reference and harmonize independent datasets (e.g., matching blood donor IDs across omics databases), the risk of patient re-identification escalates, introducing complex legal and compliance hurdles.
Governance: build vs. buy and the role of knowledge graphs
Because external data sources are frequently unstructured, inconsistent, or lack verified provenance, biopharma organizations generally refuse to use external data for GxP-level decision-making and reporting. Instead, its use is confined to secondary exploratory reporting.
This reality forces organizations to ask: Is it worth purchasing external data and investing massive effort to prove its lineage, or is it more efficient to build it internally?
To navigate this landscape, organizations are leveraging two core architectural strategies:
- Knowledge graphs: Tools like metaphactory, a Digital Science solution, are critical to building semantic ontologies, mapping disparate terminologies, and pointing autonomous AI agents directly to trusted data sources. They handle licensing, rights management, and legal boundaries.
- Provenance machines: Tools like metaphactory’s metis act as black-box provenance machines, ensuring that every claim, entity, and relationship extracted by an agent is traceable back to its origin.
Systemic collaboration is needed
Ultimately, biopharma cannot rely on literature or databases in isolation. The future of AI-driven drug discovery depends on a composable substrate where unstructured literature discoveries are programmatically harmonized with highly structured external and internal databases. Building and maintaining this substrate is not a task for any single organization—it requires deep, systemic collaboration between biopharma, biotech, academic publishers, and AI tool developers to ensure the data powering tomorrow’s agents is reliable, traceable, and GxP-compliant.
Building an AI-ready data stack is a team effort. Talk to Digital Science about how metaphactory and metis can help.
The post Grounding AI Agents: literature vs. structured databases in the biopharma data stack appeared first on Digital Science.
from Digital Science https://ift.tt/P9gblqz
The next era of AI in drug discovery
As AI moves from summarizing papers to generating scientific claims, biopharma faces a hard question: how do you trust an answer with no way to trace it back to the truth? Digital Science’s Mark Hahnel unpacks the shift at hubXchange 2026.
Keynotes & insights from AI in Drug Discovery hubXchange 2026
On September 9, 2026, leaders across the biopharmaceutical and artificial intelligence sectors gathered in San Francisco for the AI in Drug Discovery hubXchange. Digital Science’s Mark Hahnel delivered a keynote address examining how AI is altering scientific inquiry and biopharma R&D. Moving beyond basic task automation, Hahnel articulated a future centered on data provenance, agentic workflows and the assembly of an industry-wide data substrate.
Read on for a recap and key takeaways from Hahnel’s keynote.
Moving beyond ‘AI as a Tool’ to agentic workflows
Scientific research has entered the ‘4th paradigm’, where massive volumes of data must be readily available and actionable. However, the current velocity of AI adoption is accelerating at a rate that introduces friction into traditional organizational workflows. Rapid theoretical milestones highlight this momentum, such as OpenAI publishing proofs for the complex Navier-Stokes fluid mechanics equations on Twitter. The tension between independent mathematicians leveraging Codex to tackle similar challenges, and claims of unethical scooping, demonstrates the need for tools that protect IP while supporting research advancement.
Large corporations are embracing AI, transitioning from basic productivity aids to deploying AI for generating new scientific knowledge and discovering novel drugs. Room consensus at hubXchange aligned with statistics indicating over 50% enterprise adoption across major organizations. The biopharma industry has officially progressed past using isolated AI tools and entered the next phase: managing siloed data alongside specialized domain models and autonomous agentic workflows.
Offline & local models: safeguarding intellectual property
As enterprise adoption deepens, maintaining strict data security and protecting early-stage IP remain paramount. To prevent proprietary research from being inadvertently exposed or ‘scooped’ through public cloud chat windows, biopharma companies are prioritizing local models and offline data architectures.
Dedicated tools like Digital Science’s Papers AI address this demand by keeping enterprise data, local models, and analytical routines fully offline, ensuring researchers can leverage modern AI capabilities without compromising security.
The Provenance Crisis & Data Trust
As generative systems output claims at scale, biopharmaceutical organizations face a foundational challenge: Where did this data originate, and how was this specific claim validated? Grounding claims in verifiable truth is critical because core human facts reside outside the latent weights of Large Language Models (LLMs).
To achieve full traceability, organizations must back up every statement and derived insight. Hahnel highlighted the framework detailed in Digital Science’s FAIR data playbook for Pharma white paper as an essential roadmap for establishing structured, trustworthy data environments. Regulatory compliance necessitates adhering to the FDA + EMA Guiding Principles of Good AI Practice in Drug Development, which require tracking the explicit source, raw underlying data, and precise timestamps for all AI-assisted findings.
Constructing & deconstructing papers for machines
Building robust drug discovery models requires looking beyond high-level literature summaries. While cheap and accessible methods exist—such as using models like Claude to ingest titles and abstracts from PubMed—true drug discovery demands deep full-text extraction. Full text is essential to extract vital scientific nuances, including detailed methods, experimental edge cases, figures, and direct scientific contradictions.
Navigating this domain requires working within a fragmented publisher landscape, where the top 5% of publishers account for approximately 61% of all scientific publications. Existing pharma licensing agreements provide a pathway to deconstruct and reconstruct scientific papers into machine-ready structures, enhancing internal proprietary data.
Data must be structured once across workflows so it can be continuously reused rather than repeatedly extracted. Maintaining these comprehensive global databases requires continuous operational maintenance; for example, maintaining Dimensions‘ global patent database requires a workforce actively liaising with patent offices worldwide to correct inaccuracies and guarantee precision.
Four core techniques for structured data extraction
To derive locally verifiable statements and establish end-to-end data provenance, four primary computational techniques are being actively deployed:
- Mapping: Leveraging LLM-driven ontology mapping to harmonize disparate scientific terminologies across domains.
- Graphs: Building dynamic knowledge graphs that represent evolving biological relationships and entities.
- Triage: Implementing just-in-time triage and filtering to parse incoming streams of scientific literature efficiently.
- Extractors: Deploying agentic extractors designed to pull out claims, experimental methods, biological entities, and explicit relationships directly from full text.
These techniques allow organizations to extract claims and harmonize them so they are composable with internal proprietary extensions, Electronic Lab Notebooks (ELN), and existing R&D workflows.
Conclusion: the substrate is the work
The primary takeaway from Mark Hahnel’s presentation is clear: while foundational models and agent frameworks will continuously improve, the ultimate value lies in the data substrate beneath them. Grounded scholarly inference requires generating answers built upon verified external data seamlessly combined with internal enterprise assets.
Building this substrate requires deep collaboration across biopharma, biotech, academic publishers, and AI tooling providers. Models and agent frameworks will continue to evolve, but establishing the underlying, composable data substrate is the foundational work that the entire field must build together.
Ready to build the data substrate your AI strategy depends on? Explore how Digital Science’s enterprise solutions help biopharma organizations turn siloed data into trusted, structured, AI-ready assets.
The post The next era of AI in drug discovery appeared first on Digital Science.
from Digital Science https://ift.tt/Zg0Jmiy
In Life Sciences, data integrity is non-negotiable
In the age of AI, research intelligence has to begin with trusted data. The Inside Our Data series explores the foundational data infrastructure that makes trust possible.
The cost of an answer no one can explain
Enterprises rely on research intelligence to set and meet strategic objectives; intelligence is what makes an enterprise competitive. Research intelligence, as a concept, isn’t new. What is new is the enterprise’s necessary reliance on huge volumes of data—and on AI-driven insights and analysis which take that data as truth.
Enterprises are moving fast to embed AI into research, analytics, and strategic planning. Far from the zeitgeisty pilots which were largely based on frontier model usage, AI-driven intelligence now comprises foundational infrastructure that informs how decisions are made.
But for the advances and benefits this technology has already brought about, it has also brought risk. Research and AI-driven intelligence are only as trustworthy and defensible as the data they use, and not all data can withstand the necessary scrutiny of independent review.
This can pose an existential threat to research enterprises operating in regulated industries such as Life Sciences. As enterprises continue to evolve and embrace powerful new technologies, it’s more important than ever that their underlying data can stand up to audit.
In this article, we’ll look at what happens when enterprises lack data integrity, what “trustworthy” data actually means in Life Sciences, and how the right infrastructure can fortify enterprise data in the world of AI.
What happens when the data underneath a scientific conclusion can’t be checked?
In 2020, two COVID-19 studies were published—one in the Lancet and one in the New England Journal of Medicine—using data from Surgisphere, a little-known analytics firm.
But soon, there was a problem: Surgisphere refused to release its data for an independent audit. Both studies were retracted nine days apart.
The Lancet study claimed hydroxychloroquine increased mortality risk in COVID-19 patients—a finding that prompted the WHO to briefly pause a hydroxychloroquine arm of its global Solidarity trial before the retraction. The NEJM study was also retracted, but kept being cited long after: a Journal of the American Medical Association Internal Medicine analysis found 652 verified citations, with more than half of them occurring at least three months after the retractions took place.
This incident illustrates what is at risk when data can’t be audited. We don’t know why Surgisphere wouldn’t release the data. Maybe it was all fabricated, maybe it wasn’t. There’s no way to know. But it doesn’t really matter. Data that cannot be audited is contagious. Bad data doesn’t stay where it started. It moves into papers, then models. Bad data has always been contagious. AI gives it a much higher reproduction rate.
It’s likely that the initial retractions were costly and frustrating for the firms who carried out the studies. But this incident also contributed to a wave of inaccuracy in critical research areas. Data that can’t be audited can halt clinical trials, knock percentage points off a stock valuation, cause lasting reputational damage, and most seriously, negatively impact the lives of real people.
What “trusted data” really means
When it comes to defining what makes good data, enterprises aren’t starting from square one—Life Sciences has already formalized what “trustworthy” data means.
Regulators have relied on ALCOA—Attributable, Legible, Contemporaneous, Original, and Accurate—since the 1990s to assess data integrity in clinical and manufacturing contexts. More recently, guidance from bodies like the Medicines and Healthcare products Regulatory Agency and the World Health Organization extended this into ALCOA+, adding four further requirements: data should also be Complete, Consistent, Enduring, and Available. It’s a checklist built around whether a record can be verified after the fact, and it’s still required for trustworthy data today.
The related framework, FAIR—Findable, Accessible, Interoperable, and Reusable—addresses a different but equally consequential point of failure. Introduced in 2016, FAIR has had a substantial impact on how research-generating organizations think about their data: not just whether it exists, but whether it can be found, retrieved under clear terms, and reused with confidence in its provenance. FAIR doesn’t require data to be open to all—a dataset behind a paywall or access agreement can still be fully FAIR-compliant. However, in order to satisfy the requirements of the framework, it needs to be made available, in a FAIR manner, to the people who would make assertions on that data.
The Surgisphere retractions occurred because the underlying datasets were non-compliant with these frameworks. The data wasn’t available or accessible for audit, which meant we also couldn’t know if it exemplified the necessary integrity that made it suitable for use in research.
These frameworks comprise a non-negotiable baseline for Life Sciences research enterprises, but there remain grey areas which can have unintended effects on the quality of research datasets. For example, an open dataset which is seemingly FAIR and ALCOA+-compliant could be skewed toward whichever countries or funders proactively volunteer their data. In a regulated environment, this isn’t enough; passing an ALCOA+ or FAIR checklist doesn’t tell you whether a dataset is representative—curation, applied on top of these frameworks, can correct for that skew.
Data infrastructure designed to accommodate investigation
Data curation refers to the ongoing process of ensuring that data is complete and representative—a process that requires human judgment and relationships to execute. This is a foundational tenet of the datasets which comprise Dimensions by Digital Science, one of the world’s largest research and funding data repositories.
Dimensions was built around the idea that research intelligence is only useful if it can be traced across the full lifecycle it describes—not only publications, but the funding, trials, patents, and policy activity that surround them. Dimensions datasets span six linked content types: more than 165 million publications, 8.2 million grants, 74 million research datasets, 180 million patents, 976,000 clinical trials, and 2.5 million policy documents, all cross-referenced with the others.
A model surfaces a promising area of research. Don’t just take the answer. Ask:
- Who funded it?
- Which researchers produced it?
- What publications followed?
- What datasets underpin them?
- Were patents filed?
- Did it progress into clinical trials?
- Did it influence policy?
This structure enables attributability and originality under ALCOA+: publication records are enriched through full-text indexing and linked back to direct publisher partnerships, Crossref, PubMed, and other authoritative sources. The grant data comes from more than 700 funders worldwide, sourced by data experts directly from funder organizations wherever possible. Clinical trial records are pulled directly from official registries spanning every major region, so status, sponsors, and outcomes reflect the authoritative record rather than a secondhand summary. Patent data is provided by IFI Claims, curated and normalized by Digital Science teams.
Every record carries a persistent identifier and a link back to its original source, so a grant, publication, or patent is Findable and its provenance is never in question. Records are Accessible under clear, documented terms—whether that’s open data or a governed connection through a licensed platform, so users always know what they’re looking at and where it came from. And the cross-referencing between content types is what makes the data Interoperable and Reusable in practice: a grant can be traced through to the publications it funded, the datasets and patents those publications generated, and the clinical trials or policy documents that followed. Research across more than 100 countries and every major discipline reduces the blind spots that come from a literature-only view or a single-region dataset. This is data that can be audited—and that enterprises can trust to drive the decisions they make.
The final step to unlocking truly powerful and trustworthy intelligence is ensuring this data infrastructure is in sync with enterprise-specific ontologies. Pairing trusted data with semantic definitions lays the groundwork for life sciences enterprises to more safely rely on AI-driven research intelligence in the years to come.
Building trusted foundations for future AI implementations
The Surgisphere debacle exemplifies the failures that AI-assisted workflows now risk automating at scale: fluent, confident outputs based on data that doesn’t meet industry standards. Today, AI-assisted workflows are increasingly embedded in how R&D and Medical Affairs teams triage literature, surface signals, and make decisions. The efficiencies and insights to be gained from this technology are unprecedented, but this also raises the stakes: an AI working from ungoverned data doesn’t just produce a bad answer, it can introduce existential risk.
The best way to guard against such a failure—and set your company up for long-term success—is to take a two-pronged approach, pairing an enterprise-specific semantic layer, such as a knowledge graph, with data that is FAIR and ALCOA+-compliant. Digital Science offers knowledge graph infrastructure designed to grow with an enterprise via its proprietary technology, metaphacts.
By defining a semantic layer, an enterprise sets the scope for the data that AI is able to access and defines the logical relations between defined entities. This means the model can only interpret the data it is given access to in the context of an approved series of rules. This mitigates the risk of hallucinations or logical failures, and makes it simple for auditors to interrogate the pathways that led to a certain output. This is how to ensure trusted data is treated predictably by trusted models.
The result is accurate intelligence with an in-built audit trail that enterprises can trust to stand up to independent audit.
The bar for data integrity will keep rising
As AI becomes more embedded in R&D and Medical Affairs decision-making, so too will audits by regulators and internal stakeholders. Trusted intelligence starts with trusted data, and trusted data is best used in sync with foundational enterprise infrastructure.
Digital Science provides one of the world’s broadest collections of connected research intelligence—combining Dimensions, Altmetric, and IFI Claims to help enterprise organizations support analytics, strategic decision-making, innovation, and AI workflows that can be explained, audited, and defended.
The post In Life Sciences, data integrity is non-negotiable appeared first on Digital Science.
from Digital Science https://ift.tt/QRGXa1F
A double-edged sword: the growing complexity of Medical Affairs publication performance data
The variety of channels and audiences that define scientific communications reach and engagement is growing. In turn, Medical Affairs teams face diversifying data sources and tools to assess publication performance.
Compass Points: The Future of Medical Affairs is a series exploring the strategic challenges facing medical affairs teams in today’s communication landscape—and the tools that will help them get it right.
Even the most groundbreaking data cannot change clinical practice if never translated into action. As such, a fundamental purpose of scientific communications is to inform and educate on this new data, what it means, and how it can impact the real world. The challenge is how to do this effectively across multiple regions, channels, and audiences, and how to track success (or failure).
As the complexity of scientific communication scales, Medical Affairs teams rely on an expanding library of data sources and tools to analyze the performance of scientific communications tactics. Quantifying asset performance and impact directly informs strategy, and in turn, informs publication planning. We see that this feedback loop propagates the outcomes of tactical and strategic decision-making, whether these outcomes were desirable or undesirable.
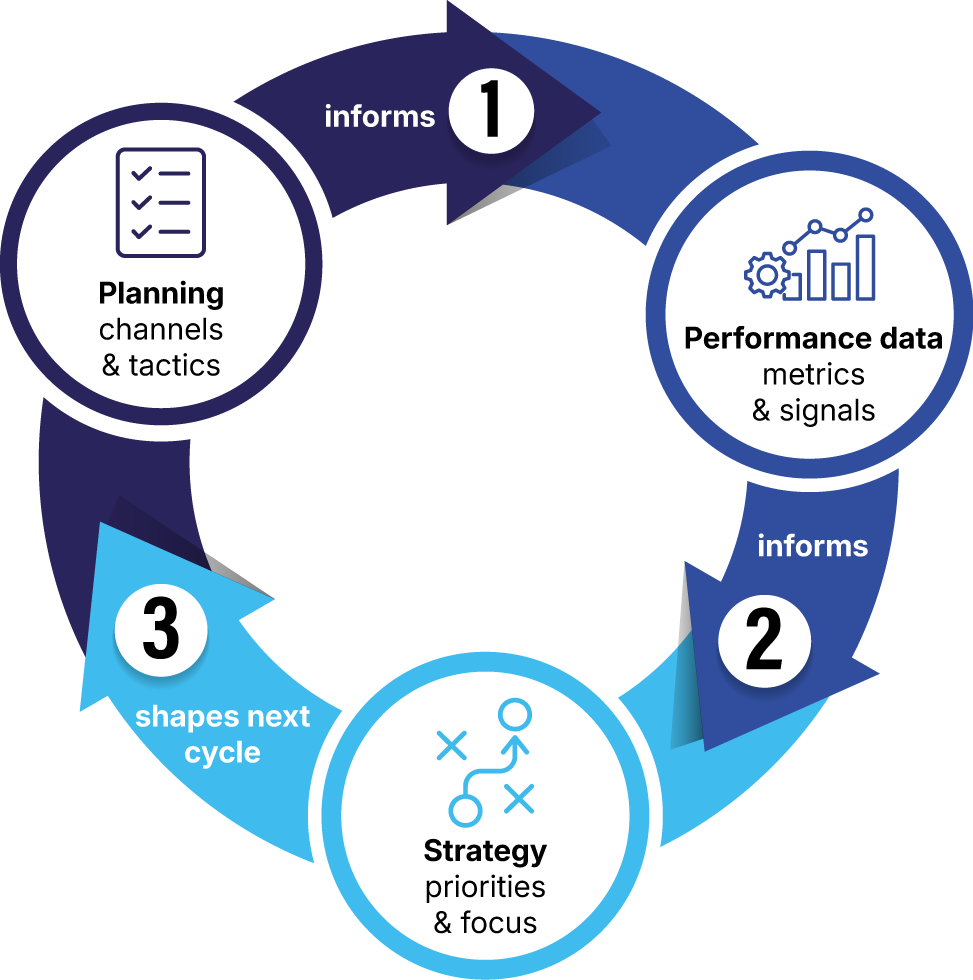
The growing availability of data sources and tools used to define publication performance is a double-edged sword: capabilities increase, but so, too, does workload. Assessments performed in different settings, at different time points, with non-standardized queries may create inconsistency in those outputs contributing to strategic decisions about publications. The value of scientific communications can be efficiently captured by measurement tools, such as Compass by Dimensions, characterized by integrated sources, standardized data, and intuitive performance benchmarking.
Limitations become visible when publication performance data sources and reporting tools are siloed.
As part of Medical Affairs scientific communications planning and evaluation, asset performance directly informs publications strategy. A growing variety of data sources and analysis tools are now available. These help determine publications’ reach and engagement, and by extension, their impact.
Citation tracking tools hold continued relevance. In what may represent a highly manual process, pertinent altmetrics must first be defined, then followed over time. Social media listening offers publication performance insights from an altogether different channel. To assess proprietary (or competitor) abstracts, posters, and podium presentations, congress trackers of varying complexity are commercially available or developed in-house. Whether for conferences, publishers, or individual journals, both the type and availability of performance metrics vary widely.
These examples are not comprehensive. As their variety suggests, publication performance data sources and reporting tools are often functionally siloed from one another. They must be evaluated in turn, and the readouts integrated, to generate a comprehensive snapshot.
Being inherently decoupled, it follows that the data sources and reporting tools illustrated here will lack technical platform interoperability. Plainly stated, they don’t communicate. As such, they are limited in their ability to provide integrated readouts and a contextual story of scientific communications asset performance.
What does this mean for user experience and workload?
Across life sciences industries, the size, structure, and distribution of Medical Affairs and publications teams differ significantly. Scientific communications strategy may be defined within the Medical Affairs functional area alone, or within a cross-functional center of excellence or integrated evidence planning team.
Where data and reporting tools are managed by a group of colleagues, only by investing time and aligning their efforts can these contributors integrate findings into a cohesive performance narrative. If such coordinating and reporting activities are repeated on a monthly basis, for example, we begin to grasp the many people-hours required. In the present era of remote work, it’s likely that these team members do not work in the same physical space, or even the same time zone. Creating the impact story requires continuous touchpoints, further decreasing efficiency.
It is important to highlight this concept of the scientific communications impact story, as creating it is just one step in the process. Another key aspect is telling that impact story effectively to leadership and other key stakeholders. How are the publication performance data contextualized? What reporting content can decision-makers expect to see, and reliably?
A holistic scientific communications performance overview, delivered on-schedule with consistent format, takes significant time and effort, whether the overview’s creator is a team or a single contributor.
In the case of a single contributor such as the publications manager or director, this colleague is solely responsible for the time-consuming, repetitive work of integrating increasingly complex data sources and tools. Expertise more impactfully invested in key project management and strategic activities is instead diverted to data analysis. The workload risks overwhelming that colleague.
Whether in (bio)pharma, biotech, or medtech organizations, this situation’s impact may be more acutely felt in publications teams serving multiple disease or product areas. In a further example, its impact is visible in small- and medium-sized life sciences companies, where publications colleagues may “wear other hats,” having broader role descriptions or functional responsibilities.
When publication performance insights are integrated from diverse sources, how does this influence their perception?
Building on this, publications teams are facing operational environments in which scientific communications performance assessment and reporting processes become overwhelming.
While these may be subject to formalized standard operating procedures, it’s more likely that practices fluctuate over time: team structures change, or publication types evolve. Inherent knowledge informs the work of integrating performance data from diverse sources, often depending on personal best practices. Processes become opaque, and as the risks of missing relevant data and of differing interpretations increase, reporting inconsistencies emerge.
Whether monitoring owned or competitor assets, publication performance reporting serves myriad purposes. These range from publication impact measurement, to downstream budget and strategy planning, to competitive intelligence. Performance reporting is meant to describe impact and value.
Should the integrated insights appear inconsistent, this perception affects stakeholders. It reflects negatively on the work and reputation of the publications or scientific communications team, the Medical Affairs team, or the integrated evidence planning team. Cross-functional partners or leadership may perceive the accumulated insights as unreliable, or even non-actionable. Over time, this hinders effective business decision-making, perceived department value, trust, and even individual working relationships.
Data integration workarounds that utilize generative artificial intelligence lack fidelity.
In the last three years, multimodal generative artificial intelligence (genAI) technologies have gained significant traction as data integrators. Their ability to instantaneously compare inputs, summarize findings, and create personalized outputs feels reassuring. With remarkable efficiency improvements, a single user can develop polished, on-brand content and dashboards in minutes.
GenAI technologies may represent a tempting solution to the challenge of publication performance data collected from such disparate sources and tools. This is especially true for life sciences organizations holding enterprise agreements that facilitate company-managed access to these technologies.
It is critical to balance the benefits of improved efficiency against the limitations of utilizing genAI as a process workaround to analyze and integrate publication performance data. Due to these technologies’ very design, they are neither able to consistently benchmark nor to track target performance metrics over time. As such, assessments remain snapshots that must be repeated according to stakeholders’ reporting requirements.
Hallucination and sycophantic responses are known challenges with the use of genAI. Outputs with publication performance data integration as their goal may be incomplete, factually incorrect, or biased. A genAI-grounded process still relies on the user to identify and supply trusted data sources. If pertinent metrics are missing, genAI-directed data integration processes cannot account for them. Alternatively, depending on how the user prompts the model, they may have the undesirable experience of hallucinated metrics or outputs.
The use of genAI to speed up integration of disparate, disconnected data sources should not come at the cost of insight fidelity. Rather, when artificial intelligence capabilities are paired with data analytics, reliable analyses require standardized, consistent data feeds from curated sources. When a publications team builds such analytics de novo, both the data sources and analytics outputs take time to verify and to trust.
Standardization and repeatability are key to successful publication performance assessment.
Capturing the value of scientific communications should not be held back by the repetitive work of reconciling disparate data sources. Nor should strategy-defining insights depend on workarounds, themselves subject to technical limitations. As well, it is worthwhile to consider the accumulated inefficiencies that these activities create for publications managers and teams.
Measurement tools that integrate data sources by their design unlock the power of user-defined search and tracking parameters. Meaningful insights are uncovered when these parameters are standardized and repeatable, tracking publication performance with consistency over time. When unique, Medical Affairs-relevant data sources come already embedded, it streamlines the work of uncovering scientific communications reach, engagement, and impact. This diversity of data is no longer an obstacle.
Compass by Dimensions captures these capabilities. Built on more than a decade of Dimensions and Altmetric data trusted by industry, it is designed to help overcome the challenge of data diversity. Compass combines publication and altmetrics into a single collaborative workflow, reducing inefficiencies, saving time, and simplifying how publications professionals and Medical Affairs teams benchmark, track, and manage publication impact and reach.
Compass by Dimensions is developed by Digital Science, an AI-focused technology company that transforms fragmented data into unified knowledge assets, leveraging AI and Knowledge Graphs to deliver structured, actionable intelligence for high-value discovery and innovation. By combining unparalleled data depth and breadth with enterprise-ready AI technology, we help leaders confidently accelerate product life cycles and secure a decisive market lead.
The post A double-edged sword: the growing complexity of Medical Affairs publication performance data appeared first on Digital Science.
from Digital Science https://ift.tt/tuWEXl6
Subscribe to:
Posts (Atom)
Popular
-
Word choice may seem out of place among the myriad factors that can influence outcomes for a complex condition like alcohol use disorder (...
-
In the first blog in this series, we explored engagement and impact readiness for the Research Excellence Framework (REF) 2029. Here, we t...
-
A new wearable device turns the touch of a finger into a source of power for small electronics and sensors. Engineers at the University of ...


